TokenMaxxing: How to Get the Most Out of Your AI Models
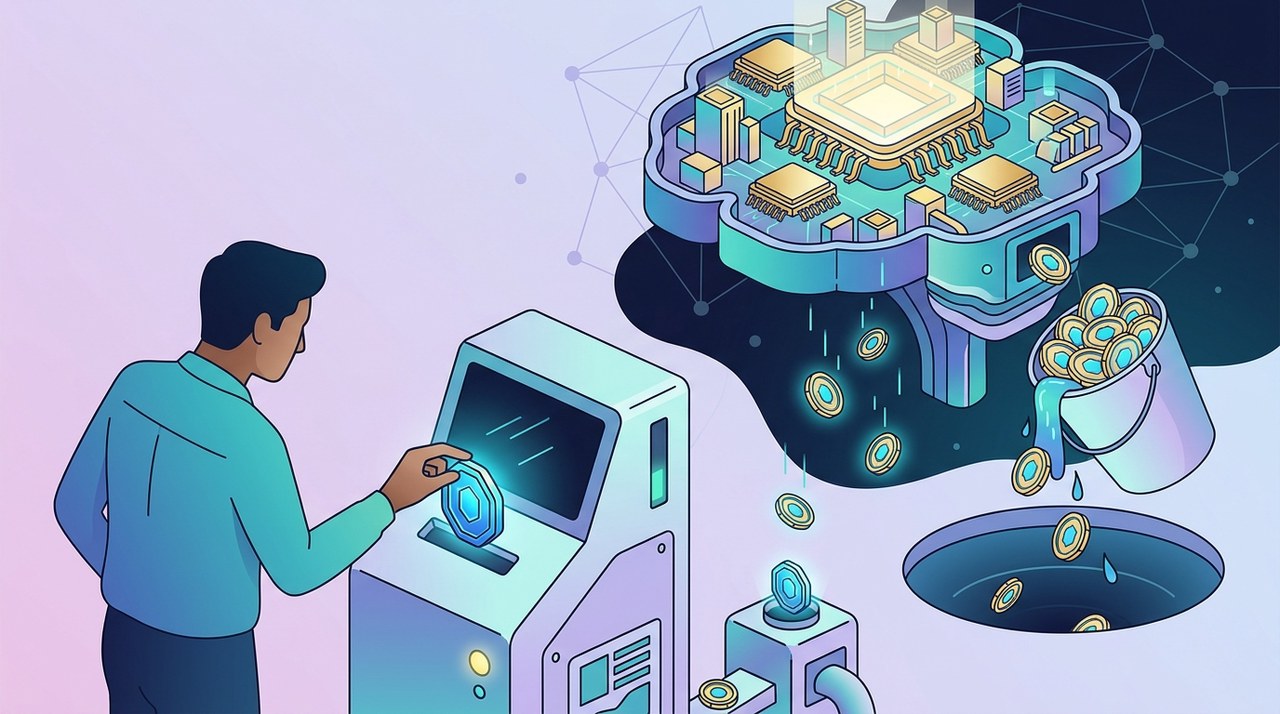
What Is TokenMaxxing and Why Should You Care?
High-end AI models like Claude Opus or top-tier GPT models are incredibly capable. However, using them for basic everyday tasks is a bit like hiring Albert Einstein just to calculate your change at McDonald's.
Many people blindly default to using the biggest and most expensive AI models for every single task. That habit leads to massive enterprise bills and causes individual users on monthly subscriptions to hit usage limits far too quickly.
The Mind-Boggling Cost of Unchecked Token Usage
To understand where your money goes, it helps to look at how AI pricing works. AI companies meter usage using tokens, which are chunks of text averaging roughly three-quarters of a word.
Flagship models cost up to 100 times more per token than smaller options. Across major AI providers, input prices range anywhere from $10 down to just $0.10 per million tokens.
The Corporate Burn Rate
Earlier in 2026, Meta employees burned through an astounding 60 trillion AI tokens in only 30 days. They were competing on an internal usage leaderboard nicknamed "Claudeonomics."
Tech columnist Gergely Orosz estimated that spending spree at roughly $900 million at Anthropic's list prices, even though Meta likely negotiated enterprise rates.
Meta was far from alone in this trend. Microsoft, Shopify, and Amazon set up similar internal token leaderboards. Nvidia CEO Jensen Huang added fuel to the movement during a March appearance on the "All-In" podcast, stating he would be "deeply alarmed" if a $500,000 engineer did not burn at least $250,000 worth of tokens.
Unsurprisingly, staff began burning tokens on silly, unproductive tasks. Amazon employees admitted to running internal AI tools on irrelevant work just to inflate their board standing, prompting a Senior VP to issue a firm memo: "Please don't use AI just for the sake of using AI."
Meanwhile, Uber burned through its entire 2026 AI tools budget in roughly four months. Bain & Company consultant Jue Wang noted to the Associated Press that countless users routinely default to high-end models even for simple tasks like drafting basic emails.
These massive spending habits explain why Anthropic's annual revenue run rate jumped from about $9 billion at the end of 2025 to over $47 billion by May, while OpenAI continues a aggressive price war to keep up.
Understanding Standard Anthropic Rates
To see how token costs multiply, take a look at standard pricing rates per million tokens:
- Haiku: $0.25 input / $1.25 output (for prompts under 100,000 tokens; longer prompts cost 5x more)
- Sonnet: $3.00 input / $15.00 output
- Opus: $15.00 input / $75.00 output
Notice that output tokens cost five times as much as input tokens across all tiers. Keeping your model responses focused saves substantial money.
How AI Agents and Automation Multiply Costs
Modern workflows are moving toward autonomous AI agents. Three core concepts help explain why automated agent bills explode so quickly.
1. The Agent Loop
An agent is an AI model equipped with tools. It thinks, searches the web or runs code, reviews the result, and loops again until it considers the task complete. On every single loop, it resends the entire conversation history, multiplying token usage rapidly.
2. Orchestration and Subagents
Complex setups use orchestration, where a manager model breaks down a prompt and hands pieces to worker models called subagents. Each worker runs its own loop with its own memory. Anthropic points out that agent teams in Claude Code running in plan mode can consume about seven times more tokens than standard chat sessions.
3. Graph Workflows
To keep loops from wandering indefinitely, developers use frameworks like LangGraph to map workflows like subway systems. Stations (nodes) do the work, while tracks (edges) direct where the request goes next, forcing models along fixed routes rather than spinning until budgets run out.
Five Beginner Tips to Cut AI Costs (Zero Coding Required)
You do not need to write code to cut your token spend right away. Here are five easy habits you can adopt directly inside your chat window.
Tip 1: Pick the Right Model for the Job
Click the model selector in your chat application and pick smaller, faster options like Haiku or mini models for summarizing, drafting emails, or rewording text. Reserve top-tier models like Opus for complex reasoning tasks where a single mistake carries real consequences.
Test five of your regular tasks side-by-side on both small and flagship models. If the small model handles them well, stick with it. Switching to lighter models on API plans can slash your bill by up to 99%.
Tip 2: Write One Good Prompt Instead of Five Bad Ones
Sending multiple follow-up tweaks like "No, just the total" forces the AI to re-read the entire chat thread every single turn. Write one detailed prompt outlining the specific job and desired response structure upfront.
"Extract the invoice number, date, vendor, and total from the text below. Keep every value exactly as written. Return one line per field, and write 'missing' if a field isn't there."
Internal testing from OpenAI revealed that concise, structured prompts achieved higher accuracy scores while burning fewer tokens.
Tip 3: Start a New Chat When You Change Topics
Because the model rereads the full chat history on every message, asking tax questions inside a long vacation planning thread makes your prompt far more expensive and confusing.
Anthropic refers to this breakdown in AI focus as context rot. Whenever you move to a new topic, start a fresh conversation.
Tip 4: Ask for the Size You Need
Since output tokens cost five times as much as input tokens on high-end models, always set concise output constraints.
Add instructions like "three bullet points, under 100 words" or "return only modified lines." Defining clear output limits keeps the model from adding unnecessary filler.
Tip 5: Try Free Options Before You Pay
Services like OpenRouter connect to hundreds of models and provide a free router that directs queries across roughly 20 zero-cost models. You can also run models locally on your machine using tools like LM Studio or Ollama if you have an Apple M-series Mac or a graphics card with 8GB of VRAM.
Platforms like Hermes and Nvidia offer solid collections of no-cost models. While you should avoid building key systems on free tiers that could disappear, practicing prompts on free tiers helps you refine tasks before spending money. Always review privacy policies before sharing sensitive information.
Extra Beginner Quick Hits
- Disable extended thinking: Turn off extended thinking for basic questions, or reduce effort settings on newer models. Anthropic bills the full reasoning chain as output tokens—including steps hidden from view.
- Set spending caps: Subscribers on Claude Pro or Max who use usage credits can set strict monthly spending limits under Settings > Usage.
Intermediate Tips: Keep Your Agents from Over-Reading
For developers using terminal agents like Anthropic's Claude Code, agents can quickly drain resources by scanning irrelevant files.
Tip 6: Start Cheap and Upgrade on Failure
Use the `/model` command to set Sonnet as your default, and upgrade to Opus only after Sonnet fails twice at a task. For simple background work, set `model: haiku` in subagent settings files.
Tip 7: Clear History Between Tasks
Run `/clear` when switching to an unrelated task to wipe old history for free.
If you must keep key details, use `/compact` alongside specific instructions, such as `/compact keep the database decisions`. Use compaction sparingly because the compacting action itself runs an AI request.
Tip 8: Let Code Handle the Math
Pasting a 5,000-row spreadsheet into chat forces the AI to read thousands of lines, and it can still miscount. AI models are language generators, not dedicated calculators.
Ask the model to generate a short script or formula instead, execute that code on your own machine, and feed only the final output back to the model.
Tip 9: Trim Your MCP Tools
Model Context Protocol (MCP) servers attach tools like GitHub or Google Drive to your agent. However, each connected plugin appends tool names and instructions to every single prompt window.
Use `/context` to inspect what is consuming memory and `/mcp` to disable unused plugins. Anthropic showed that stripping unnecessary tool definitions dropped an agent's token consumption from 150,000 down to just 2,000 tokens.
Extra Intermediate Quick Hits
- Track usage: Run `/usage` regularly to monitor exact token consumption.
- Keep instructions concise: Keep project context files like `CLAUDE.md` or `Soul.md` under 200 lines.
- Use Plan Mode: Press `Shift+Tab` to enter plan mode before executing large file edits. Review the agent's plan upfront, and press `Esc` if it goes off track.
- Dial down effort: Use `/effort` to turn down reasoning levels for simple work like variable renaming.
Advanced System Guardrails for Developers
Imagine processing 1,000 invoices averaging 2,000 tokens each to get 200-token answers. Running this baseline job costs around $30 on Fable 5.1 compared to $0.30 on Haiku 5.5—before applying any advanced tricks.
Tip 10: Cache Fixed Instructions
Place static prompts first and flag them for prompt caching. In Anthropic's API, this involves adding one extra field to your request body:
"system": [{"type": "text", "text": "Your invoice instructions...", "cache_control": {"type": "ephemeral"}}]
Reading cached context costs a fraction of standard input rates, though writing to the default five-minute cache has a small initial cost. Check the `cache_read_input_tokens` field in API responses to confirm caching is working.
Tip 11: Batch Non-Urgent Requests
Both OpenAI and Anthropic offer a 50% discount on batch requests, with OpenAI guaranteeing results within 24 hours. Submitting 1,000 invoices in a single batch file slashes costs in half.
Tip 12: Put Agents on a Leash
Define clear stop conditions, set maximum step counts, and enforce spending limits on every automated run. Claude Code supports a `--max-budget-usd` flag for scripted agent executions.
Companies like Shopify deploy automatic circuit breakers that cut off developer access if spending spikes unexpectedly within a single day, protecting against runaway loops.
Extra Advanced Quick Hits
- Position key data strategically: Place critical details at the very beginning or end of long prompts. A Stanford study revealed that models struggle most to recall information buried in the middle.
- Selective verification: Use a second reviewer model only when errors carry high financial costs, such as checking legal contracts or payment figures.
- Set hard API caps: Establish firm spend caps in OpenAI's API dashboard, as standard email spend alerts notify you without shutting off traffic.
The Jevons Paradox: Why Cheaper AI Costs More Overall
To test these techniques, make the cheapest capable model your default for one week and compare your total spend. On the 1,000-invoice benchmark, smart model routing dropped total cost from $30 down to $3.90—even after paying Opus 5.5 to redo 300 failed attempts.
Interestingly, lower token prices have not reduced overall AI spending. Silicon Data's Token Expenditure Index shows individual token prices fell over 90% since 2023, yet overall spending on large language models has doubled since late 2025.
Economists refer to this phenomenon as the Jevons paradox. When a resource becomes significantly cheaper and more efficient, total usage spikes because people adopt it across far more tasks.
A Bain & Company brief from June confirmed this trend: while average token costs halved between December 2024 and December 2025, total token consumption grew by 450%.
Falling prices work to your advantage as soon as you stop wasting tokens. By adopting these tokenmaxxing habits, your AI workflows become far cheaper and significantly more productive at the exact same time.
Latest blog posts


Ethereum Derivatives Flash Mixed Signals as Market Volatility Continues
Ethereum derivatives show a complex picture as futures open interest remains above $30 billion while long liquidations rise.
|

Solana Uptime Hits 2 Years, Fidelity Notes Risks
Solana has achieved two years without mainnet outages, though Fidelity highlights key areas requiring ongoing observation.
|

David Schwartz Warns Crypto Users About SecuX Wallet Scam
Ripple CTO Emeritus David Schwartz raised an urgent warning after uncovering a push notification scam targeting secret seed phrases.
|